Security

Self-Reinforcing Memory Loops in AI Agents: Causes and Fixes

Self-Reinforcing Memory Loops in AI Agents: Causes and Fixes

When remembered conclusions become new evidence.

Persistent memory turns an agent from a re-explained tool into one that carries context forward — but it opens a failure mode stateless chat avoids: an interpretation can become memory, retrieved as fact, and justify a stronger version of itself.
Data Gravity: The Real Cost of API-First AI

Data Gravity: The Real Cost of API-First AI

Why your AI stack gets stickier every month.

Every API call feels like a simple transaction - until enough of them accumulate that your fine-tuning data, evaluation harnesses, and tool schemas are all shaped around one vendor, and switching stops being a routing change.

LLM Guardrails in Practice: What Actually Works

LLM Guardrails in Practice: What Actually Works

Control the risk, not just the model.

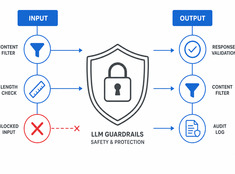
LLMs are unpredictable. They hallucinate, leak data, generate harmful content, or refuse legitimate requests. Guardrails constrain model behavior without sacrificing capability.