LLM

LLM ASICs and specialized inference chips (why they matter)

LLM ASICs and specialized inference chips (why they matter)

ASICs and custom silicon push LLM inference speed and efficiency

The future of AI is not only about smarter models. It is also about silicon that matches how those models are actually served. Specialized hardware for LLM inference is following a path reminiscent of Bitcoin mining’s move from GPUs to purpose-built ASICs, only with harder constraints because models and precision recipes keep evolving.

DGX Spark vs. Mac Studio: Price-Checked Look at NVIDIA's Personal AI Supercomp

DGX Spark vs. Mac Studio: Price-Checked Look at NVIDIA's Personal AI Supercomp

Availability, real-world retail pricing across six countries, and comparison against Mac Studio.

NVIDIA DGX Spark is real, on sale Oct 15, 2025, and targeted at CUDA developers needing local LLM work with an integrated NVIDIA AI stack. US MSRP $3,999; UK/DE/JP retail is higher due to VAT and channel. AUD/KRW public sticker prices are not yet widely posted on 15/10/2025. The 29/10/2026 check is in the later street-price section.

Ollama Enshittification - the Early Signs

Ollama Enshittification - the Early Signs

My view on current state of Ollama development

Ollama has quickly become one of the most popular tools for running LLMs locally. Its simple CLI, and streamlined model management have made it a go-to option for developers who want to work with AI models outside the cloud.

Chat UIs for Local Ollama Instances

Chat UIs for Local Ollama Instances

Quick overview of most prominent UIs for Ollama in 2025

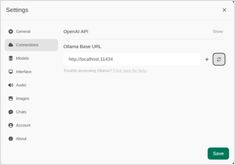
Locally hosted Ollama allows to run large language models on your own machine, but using it via command-line isn’t user-friendly. Here are several open-source projects provide ChatGPT-style interfaces that connect to a local Ollama.